Harry Potter hat voice
Autonomous's robot, Lamp, puts on a sorting hat and talks in character, voiced by Phonon.
Introducing
Gradium's open-weight text-to-speech, small enough to ship in any app. Private, and it works offline.
Already trusted by
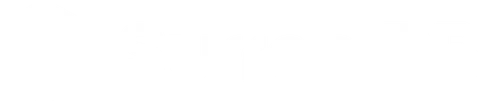
1.7%
Phonon 31m · English Tested on 500 sentences that other models get wrong: phone numbers, email addresses, postal codes.
Phonon 1.0
Phonon 31m
Phonon 40m
Phonon 40m multilingual
Phonon 31m
Phonon 40m
Phonon 40m multilingual
Where it runs
Laptops, desktops, Android phones, even a Raspberry Pi 5. No graphics card needed.
On Apple's own AI chip, through a Swift package. Up to 22× faster than real time on an iPhone 16 Pro.
Runs in the visitor's browser, so their text never leaves their device. The demo at the top of this page is it.
When there is one, for the fastest speech: NVIDIA, Apple, Vulkan or WebGPU, chosen when you build it.
Compatible with

Paste one of these prompts into your coding agent and it will read the README, build Phonon and make it speak. Or take the code.
Set up Phonon, Gradium's on-device text-to-speech, from https://github.com/gradium-ai/xn-ptts.
Read the README first and follow it over anything you assume.
1. Install the Rust CLI from the repository root with
cargo install --path ptts --locked --features cli.
2. Point MODEL_DIR at the model folder (config.json, model.q8.gguf,
tokenizer.json and the voices).
3. Synthesize "Hello world" with --lang en --quant q8 --voice Freya
to out.wav.
Verify the file plays and tell me how to change the voice.
Text in, a WAV out. The fastest way to hear it.
Autonomous's robot, Lamp, puts on a sorting hat and talks in character, voiced by Phonon.
NVIDIA Magpie TTS meets Gradium Phonon: two open models in a scripted dialogue, Magpie in Adi's voice and Phonon in Sterling's.
Proust's Du côté de chez Swann, read aloud page by page, with an Italian translation to read and hear alongside the French.
A sci-fi video game on a desert planet, its voices generated by Phonon on the player's own machine.

Phonon on an Apple Watch with Wi-Fi switched off, talking you through a coffee brew step by step, entirely on the wrist.
An iPhone app that counts your reps out loud and keeps you going, with no signal needed.
A Chrome extension that reads any text on the web aloud, with Phonon running in the browser.
[ 1 ] Creazione di Adamo, by Michelangelo Buonarroti. Date: c. 1511, part of the ceiling painted 1508-1512. Material: fresco. Dimensions: 280 × 570 cm. Current location: Cappella Sistina, volta, Musei Vaticani, Vatican City.
[ 2 ] Les trois Grâces. Artist: unknown; Roman, with restorations by Nicolas Cordier and Amainci, 1609. Date: 2nd century AD (?). Material: marble, probably Greek. Dimensions: h. 123 cm, w. 86 cm, d. 29 cm. Current location: Musée du Louvre, Aile Sully, Salle 348, Paris. Inventory number: Ma 287; MR 211; N 642.
[ 3 ] Victoire de Samothrace. Artist: unknown, Rhodes (?). Date: c. 200-175 BC. Material: Parian marble for the figure, grey Lartos marble for the ship. Dimensions: h. 328 cm overall. Current location: Musée du Louvre, Aile Denon, Escalier Daru, Salle 703, Paris. Inventory number: Ma 2369; NIII 2447; MNB 2118; MNC 1433.
[ 4 ] Portrait de Juliette Récamier, née Bernard (1777-1849), by Jacques-Louis David. Date: 1800. Material: oil on canvas. Dimensions: h. 174 cm, w. 244 cm. Current location: Musée du Louvre, Aile Denon, Salle 702, Salle Daru, néoclassicisme, Paris. Inventory number: INV 3708; C 124.